The least useful debate about AI in social media is whether it should run everything or nothing. Real teams have dozens of steps with different levels of risk. Collecting approved source material is not the same as inventing a product claim. Formatting a draft for another channel is not the same as publishing a response during a crisis.
An AI agent becomes useful when it can pursue a bounded outcome across several steps, use approved tools, inspect the result, and ask for help when necessary. It becomes dangerous when the boundary is vague, the context is stale, or a confident output is mistaken for a verified one.
The operating question is therefore not “How autonomous should our AI be?” It is “Which decisions can we safely delegate under which conditions?”
The short version
- Break the workflow into decisions and actions, then assign risk by consequence and reversibility.
- Give an agent a versioned context packet: audience, voice, claims, sources, campaign facts, channel rules, and explicit exclusions.
- Separate read, draft, approve, schedule, and publish permissions. Tool access should match the task, not the agent’s theoretical capability.
- Require evidence for factual claims and structured outputs for handoffs.
- Keep people accountable for strategy, sensitive judgment, material claims, and higher-risk publication.
- Evaluate the complete workflow: accuracy, brand fit, escalation quality, operational reliability, and time saved after review.
Start with low-risk assistance, observe real failure modes, and expand authority deliberately. Autonomy should be earned through evidence.
Distinguish an agent from ordinary automation
Traditional automation follows a predefined rule: when an item reaches “approved,” schedule it for a particular time. Generative assistance produces an output: summarize this transcript or draft five hooks. An agent can select and sequence actions toward an outcome: inspect the brief, retrieve approved sources, create channel variants, validate required fields, and route the package for review.
These approaches can coexist:
| Approach | Best for | Example |
|---|---|---|
| Deterministic automation | Stable, predictable transitions | Notify the owner when review is overdue |
| Generative assistant | A bounded creative transformation | Rewrite an approved idea as a shorter draft |
| Agentic workflow | Multi-step work with observable choices | Build a campaign package from approved sources |
Do not use an agent where a fixed rule is safer and easier to audit. “Publish at the approved time” should be deterministic. “Identify which approved customer proof best supports this brief” may benefit from reasoning, provided the evidence remains visible.
Map the workflow by risk
List the steps in your current social media operating system, including the invisible work between tools. For each step, assess:
- consequence if wrong;
- whether the action is reversible;
- sensitivity of the data involved;
- need for current external information;
- ambiguity of brand or legal judgment;
- ability to verify the output automatically;
- scope of any external side effect.
Then assign a working tier.
Low risk: tagging content, transcribing owned recordings, summarizing approved material, checking required fields, or assembling performance data without external action.
Medium risk: proposing topics, drafting copy, adapting a message for another network, recommending schedule changes, or responding to routine comments as a draft.
High risk: making unverified claims, publishing to an external account, accessing sensitive customer information, replying to conflict, changing permissions, spending budget, or deleting content.
Risk depends on context. Scheduling a pre-approved evergreen post may be routine. Scheduling an executive statement during an unfolding event is not.
Build a versioned context packet
“Write in our brand voice” is not sufficient context. An agent needs a compact, governed source of truth that can be attached to every relevant task.
Include:
- Audience: roles, situations, knowledge level, needs, and language to avoid.
- Brand voice: concrete characteristics, positive and negative examples, vocabulary, formatting norms, and accessibility requirements.
- Strategy: business objective, channel role, content pillars, and current priorities.
- Campaign facts: approved message, dates, offers, destinations, calls to action, and responsible owner.
- Claim ledger: approved factual statements, evidence links, validity dates, regions, and prohibited extrapolations.
- Channel constraints: account identity, length, media specifications, link behavior, and platform-specific conventions.
- Policy: sensitive topics, legal or regulatory review rules, escalation triggers, and prohibited actions.
Give the packet an owner, version, and review date. If the agent cannot identify which version it used, the team cannot explain why an output was produced.
Context should be retrieved by relevance, not poured into every prompt. A launch drafting task needs campaign facts and brand rules. A reporting task needs metric definitions and experiment history. Excess context can hide the instructions that matter.
Write a task contract, not a magic prompt
A reliable agent task should specify the outcome and the boundaries around it.
Use this structure:
Objective: the concrete artifact or state to produce.
Inputs: approved sources and where to find them.
Allowed actions: tools and data the agent may use.
Forbidden actions: especially publication, deletion, external messaging, or unsupported claims.
Quality rules: audience, tone, evidence, accessibility, and channel requirements.
Output schema: fields, statuses, citations, and confidence or unresolved questions.
Stop conditions: missing evidence, conflicting instructions, sensitive topic, or tool failure.
Reviewer: the person or role accountable for the next decision.
For example, an agent may be asked to create three platform-native variants from an approved source article, cite the paragraph supporting every material claim, mark unsupported requests, and save the drafts for review. It may not publish, modify the source, or infer customer results.
That contract is reusable. A clever one-off prompt is not an operating model.
Separate permissions by capability
Tool access should follow least privilege. Do not give one general-purpose agent permanent access to research, customer data, every brand account, publishing, analytics, and deletion simply because it may need those tools someday.
Separate capabilities such as:
- read approved content;
- search an internal knowledge base;
- draft and edit within a workspace;
- request a review;
- read account metadata;
- schedule an approved item;
- publish immediately;
- reply externally;
- modify or delete live content.
Scope access by brand, account, environment, and duration where possible. A campaign agent for one product should not be able to publish to a different brand’s account. A draft task should not inherit publish permission.
Human approval is not a substitute for access control. People can miss errors. The system should make an unauthorized action impossible, not merely discouraged in instructions.
Design human checkpoints around decisions
“Human in the loop” can become a meaningless claim if the human sees a hundred drafts without context and clicks approve. A useful checkpoint presents the decision clearly.
The reviewer should see:
- the original objective and audience;
- the exact proposed content and destination account;
- source evidence for material claims;
- differences from the source or previously approved version;
- policy flags and unresolved questions;
- planned timing and other campaign posts;
- the action that approval will authorize.
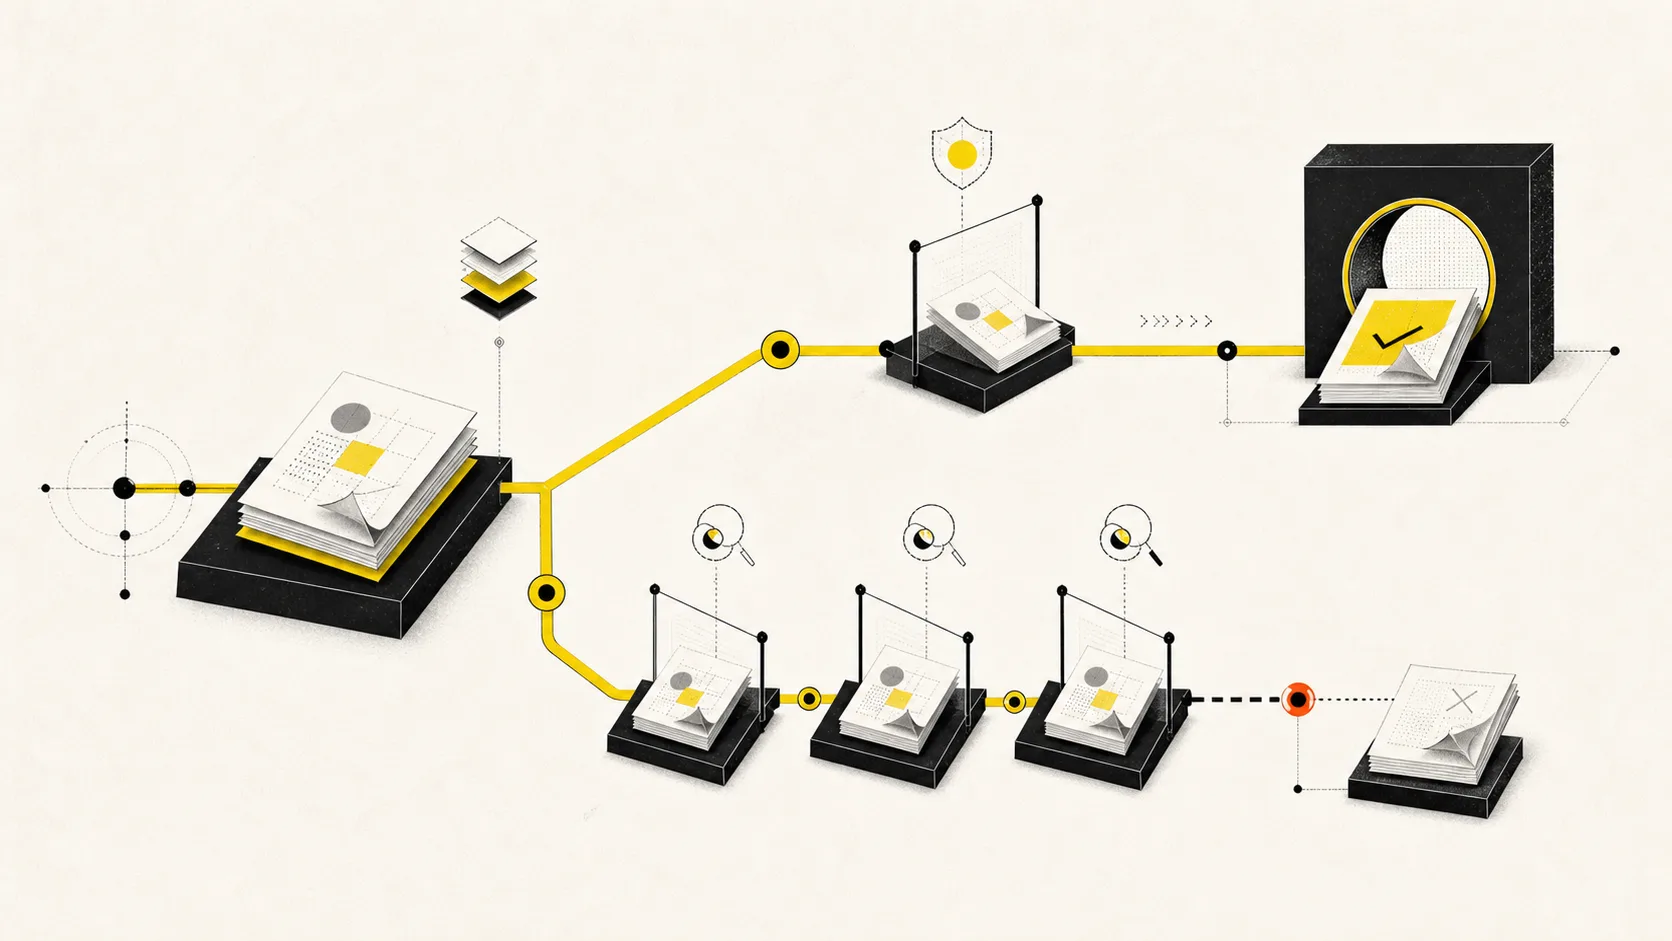
Use approval tiers. Routine, low-risk adaptations may need an editor. A pricing claim may need the product owner. Regulated language may need a specialist. A crisis response should follow a separate escalation path.
Do not ask humans to re-perform the agent’s entire task. Ask them to exercise the judgment the system intentionally reserved for them.
Keep claims grounded and traceable
Social content compresses ideas, which makes unsupported certainty especially easy. Require the agent to attach a source to factual claims before prose is polished.
A claim record can include:
| Field | Purpose |
|---|---|
| Claim | The exact assertion in the draft |
| Source | Approved document or system record |
| Evidence | Relevant section or data point |
| Scope | Product, region, audience, and time period |
| Status | Verified, needs review, or unsupported |
| Owner | Person accountable for approval |
If evidence is unavailable, the correct output is not a more plausible sentence. It is a visible unresolved state.
For current events and platform behavior, require fresh retrieval from authoritative sources and record the retrieval date. An agent’s internal knowledge is not proof that a rule still applies.
Make channel adaptation a controlled transformation
An agent is well suited to adapting one approved message across channels, but only if it preserves the message contract.
Give it:
- the canonical claim and source;
- the role of each channel;
- audience expectations by channel;
- allowed changes to framing, length, format, and call to action;
- facts and language that must not change;
- examples of strong native execution.
Require a change summary with each variant. A reviewer can then see that the LinkedIn version adds professional context, the short-form video uses a demonstration, and the concise network version removes detail without altering the claim.
This process complements a platform-native publishing workflow. The agent creates controlled differences; it does not flatten every channel into the same caption.
Test the workflow before granting external action
Evaluate agents with representative tasks, not only polished demonstrations. Include ordinary cases, ambiguous requests, missing sources, conflicting rules, and tool failures.
Score at least five dimensions:
- Factual accuracy: Are claims supported and scoped correctly?
- Instruction adherence: Did the agent respect allowed actions and stop conditions?
- Brand fit: Does the output match the defined audience and voice without mimicry or clichés?
- Escalation quality: Did it recognize uncertainty and send the right context to a person?
- Operational reliability: Are outputs complete, correctly routed, and free of unintended side effects?
Also measure review effort. A draft delivered quickly is not a productivity gain if an editor spends longer verifying and rewriting it than creating it manually.
Keep a regression set of real failure cases. Whenever an agent invents a claim, uses the wrong account, loses a required field, or escalates poorly, add a sanitized version to the evaluation suite.
Roll out authority in stages
A practical rollout can move through four stages:
Stage 1: Observe
The agent reads the existing workflow and proposes outputs, but a person performs every external action. Compare its decisions with actual team decisions.
Stage 2: Draft
The agent creates structured drafts and routes them into the normal approval workflow. It has no publish access.
Stage 3: Prepare
The agent may create channel variants, validate assets, populate scheduling fields, and recommend timing. A person approves the exact package and destination.
Stage 4: Execute bounded actions
The agent may perform a narrow external action when explicit conditions are satisfied—for example, schedule an already approved item to a specific account. Log the authorization, inputs, tool response, and final state.
Expansion should depend on observed quality and incident history. Do not move stages simply because the integration is technically available.
Plan for failures and safe recovery
Agent failures are not limited to bad copy. They include stale context, partial tool execution, duplicated actions, permission changes, unavailable providers, and an agent continuing after a prerequisite failed.
Define:
- a unique identifier for every task and publish attempt;
- explicit lifecycle states rather than a generic “done”;
- idempotency rules to prevent duplicate external actions;
- timeouts and bounded retries;
- an audit log of inputs, decisions, approvals, and tool results;
- a kill switch or permission revocation path;
- an incident owner and communication route;
- a recovery procedure for partial multi-channel execution.
If an agent schedules three of four channel variants, the system must not quietly mark the campaign complete. It should preserve the successful receipts, identify the failed destination, and ask for the defined recovery decision.
A launch checklist for an AI-assisted workflow
Before launch, confirm:
- the task has a named owner and measurable outcome;
- the context packet is current and versioned;
- approved sources and claims are distinguishable from suggestions;
- access is scoped to the required accounts and actions;
- external side effects require the intended level of approval;
- outputs use a consistent schema and expose uncertainty;
- representative and adversarial cases have been tested;
- logs are sufficient to reconstruct an action;
- retry and duplicate behavior is defined;
- reviewers know what they are accountable for;
- rollback and incident procedures are documented;
- there is a review date for keeping, changing, or retiring the workflow.
AI can remove repetitive coordination without removing human responsibility. The best system is not the one that appears most autonomous. It is the one that creates reliable leverage while making authority, evidence, and accountability unmistakable.
Frequently asked questions
Should an AI agent be allowed to publish social posts automatically?
Only for a narrow, tested class of content with explicit approval rules, scoped account access, traceable inputs, and safe failure handling. High-risk, sensitive, or materially changed content should remain subject to human review.
What social media tasks are safest to automate first?
Start with reversible, low-risk work such as classification, source summarization, brief completion checks, draft variants, and report assembly. These reveal context and quality problems before the agent receives external-action permissions.
How do we keep AI content on brand?
Use a versioned context packet with concrete voice rules, audience detail, approved examples, exclusions, and evidence. Evaluate output against a rubric and track reviewer edits. A prompt asking the model to “sound human” is not adequate governance.
Can AI agents respond to comments and messages?
They can triage or draft routine responses, but public replies can carry reputational, privacy, and support risk. Define sensitive topics and escalation triggers, restrict access, and require review until performance is proven for the exact use case.
How should we measure whether an AI workflow is successful?
Measure complete-cycle quality: accuracy, brand fit, escalation behavior, incident rate, review time, throughput, and the value of the resulting content. Time saved before review is not enough if corrections or risks increase later.